Workstation Edition
NVIDIA RTX PRO 6000 Blackwell Workstation Edition
Best when one card should run flat out. It wants a roomy case and a big power supply.
In a Pro workstation, when one card should run at full power. We choose it with you.
One NVIDIA RTX PRO 6000 Blackwell graphics card (GPU) with 96 GB of memory, in a workstation your whole team shares. Set up in Pune and tested on the model you will run; nothing leaves your office.
32 colleagues asking in the same moment each got about 63 tokens a second, a dozen times reading pace, on the Pro workstation we built and timed.
Each bar is one person’s reply stream, in tokens per second (a token ≈ ¾ of a word); the white mark is human reading pace. “At once” counts people pressing send together, which is far fewer than your headcount on a normal day. Give us that headcount and we size the machine to it.
1 person
124tokens a second
White line: reading speed, about 5 tokens a second
First word appears in 0.05 seconds
8 people
117tokens a second, each
First word appears in 0.15 seconds
32 people
63tokens a second, each
First word appears in 0.28 seconds
The load: forty work-style prompts (code, explanation, drafting), 512-token replies, fired by 1, 8 and 32 simulated users together after a warm-up pass. Qwen3.8 27B ran in its 4-bit NVFP4 build on vLLM 0.29, with the model’s own speculative decoding guessing a few tokens ahead.
“Each person” is one user’s rate while their reply streams. “All together” spans the whole run, including the gap before each reply begins, which is why it is under 32 × 63.
The card stayed pinned at its 300 W limit and peaked at 70 °C.
| People at once | Each person | All together | First word |
|---|---|---|---|
| 1 | 124 tok/s | 124 tok/s | 0.05 s |
| 8 | ~117 tok/s | 790 tok/s | 0.15 s |
| 32 | ~63 tok/s | 1,752 tok/s | 0.28 s |
On one card, everything up to about 120 billion parameters. Only the giants, like DeepSeek R1, need a GPU server.
The B number is the model’s size in billions of parameters; more usually means better answers and more memory. A row’s speed is for a single user unless it says more.
The workhorse size for chat, documents and code. Qwen3.8 27B is what we time.
Fits, 74 GB to spareAbout 22 GB of the 96
124tokens a second alone; 63 each when 32 share it
Our test, Sep 2026
Sharper reasoning and writing, e.g. Llama 3.3 70B.
Fits, with room for usersAbout 48 GB at 4-bit
32tokens a second for one user. Not yet timed for a group; we time it on your headcount first
Someone else’s test (Database Mart)
gpt-oss 120B wakes only a small slice of itself per word, which is how it can outpace a 70B model.
Still one cardUnder 80 GB
163tokens a second for one user, on the 600 W edition, not the Max-Q in our build
Someone else’s test (StorageReview)
Hundreds of billions of parameters, spread over many cards.
Beyond one cardA multi-GPU server holds them
GPU servers are quoted at ₹64 lakh–2.1 crore
Needs a GPU server
Asking a model questions is light work next to retraining it: fine-tuning a 70B model on company data wants two of these cards, in a Multi-GPU workstation. The 70B and 120B speeds come from other people’s published tests; our own runs of those are still to come.
NVIDIA makes the RTX PRO 6000 in three versions. All three have the same chip and the same 96 GB of memory. The difference is power, cooling and where the card lives, and we choose it with you.

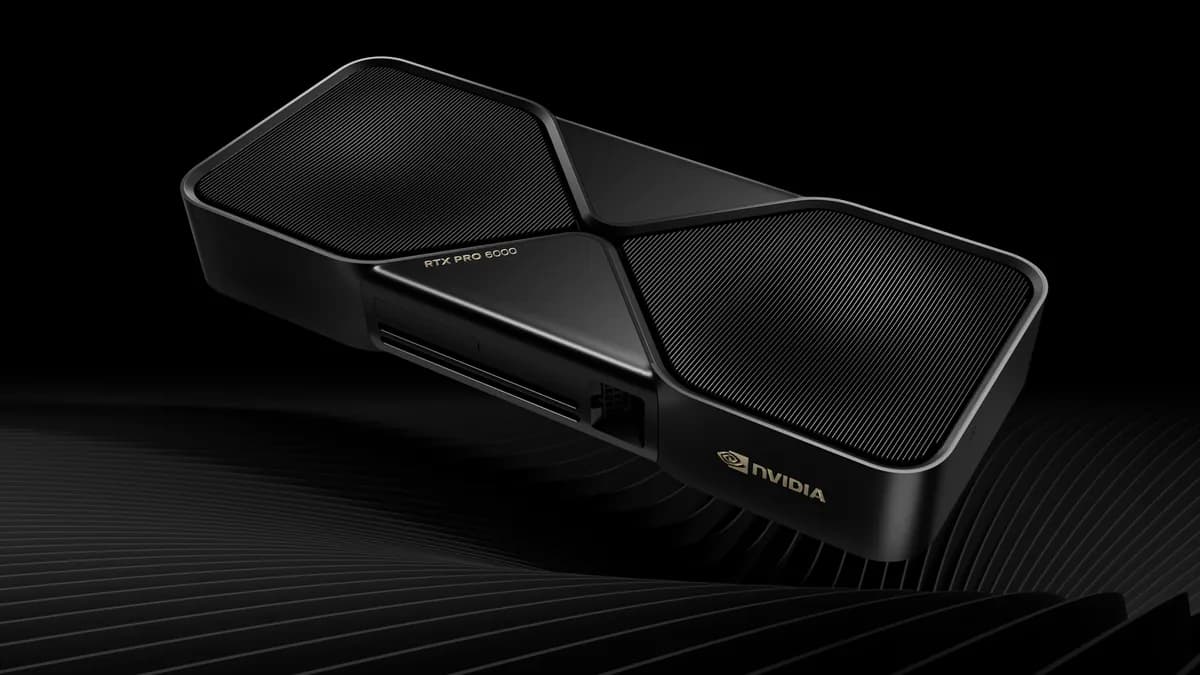
NVIDIA RTX PRO 6000 Blackwell Workstation Edition
Best when one card should run flat out. It wants a roomy case and a big power supply.
In a Pro workstation, when one card should run at full power. We choose it with you.

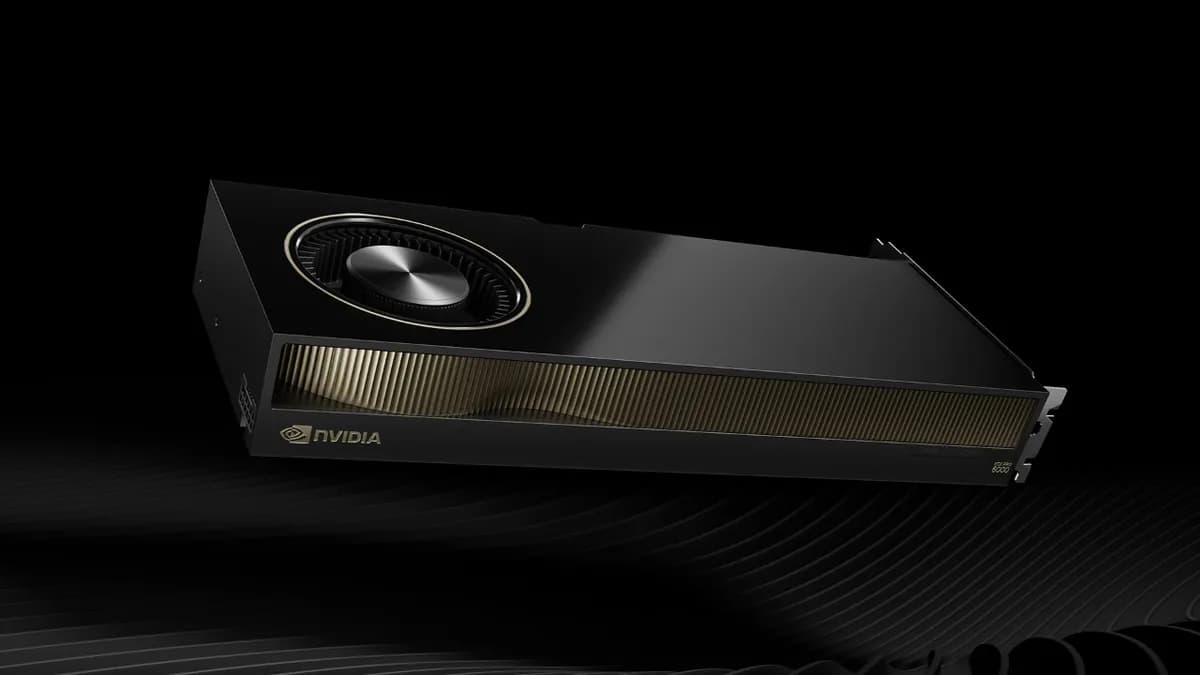
NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition
Best when you may add more cards later. Its heat leaves the case, so cards can sit side by side.
Our Pro workstation, and the two-card workstation. See multi-GPU
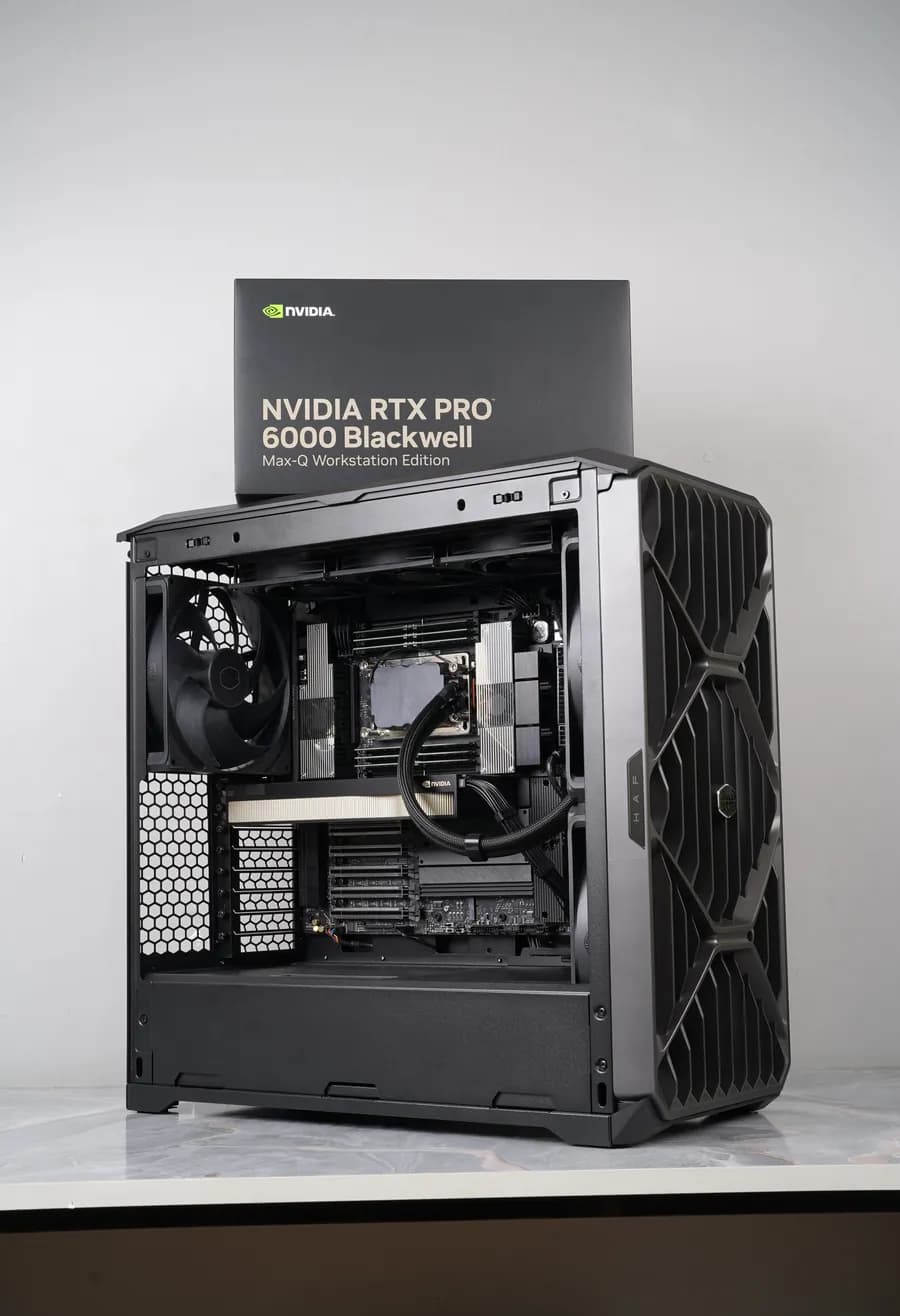
The one in the machine we built
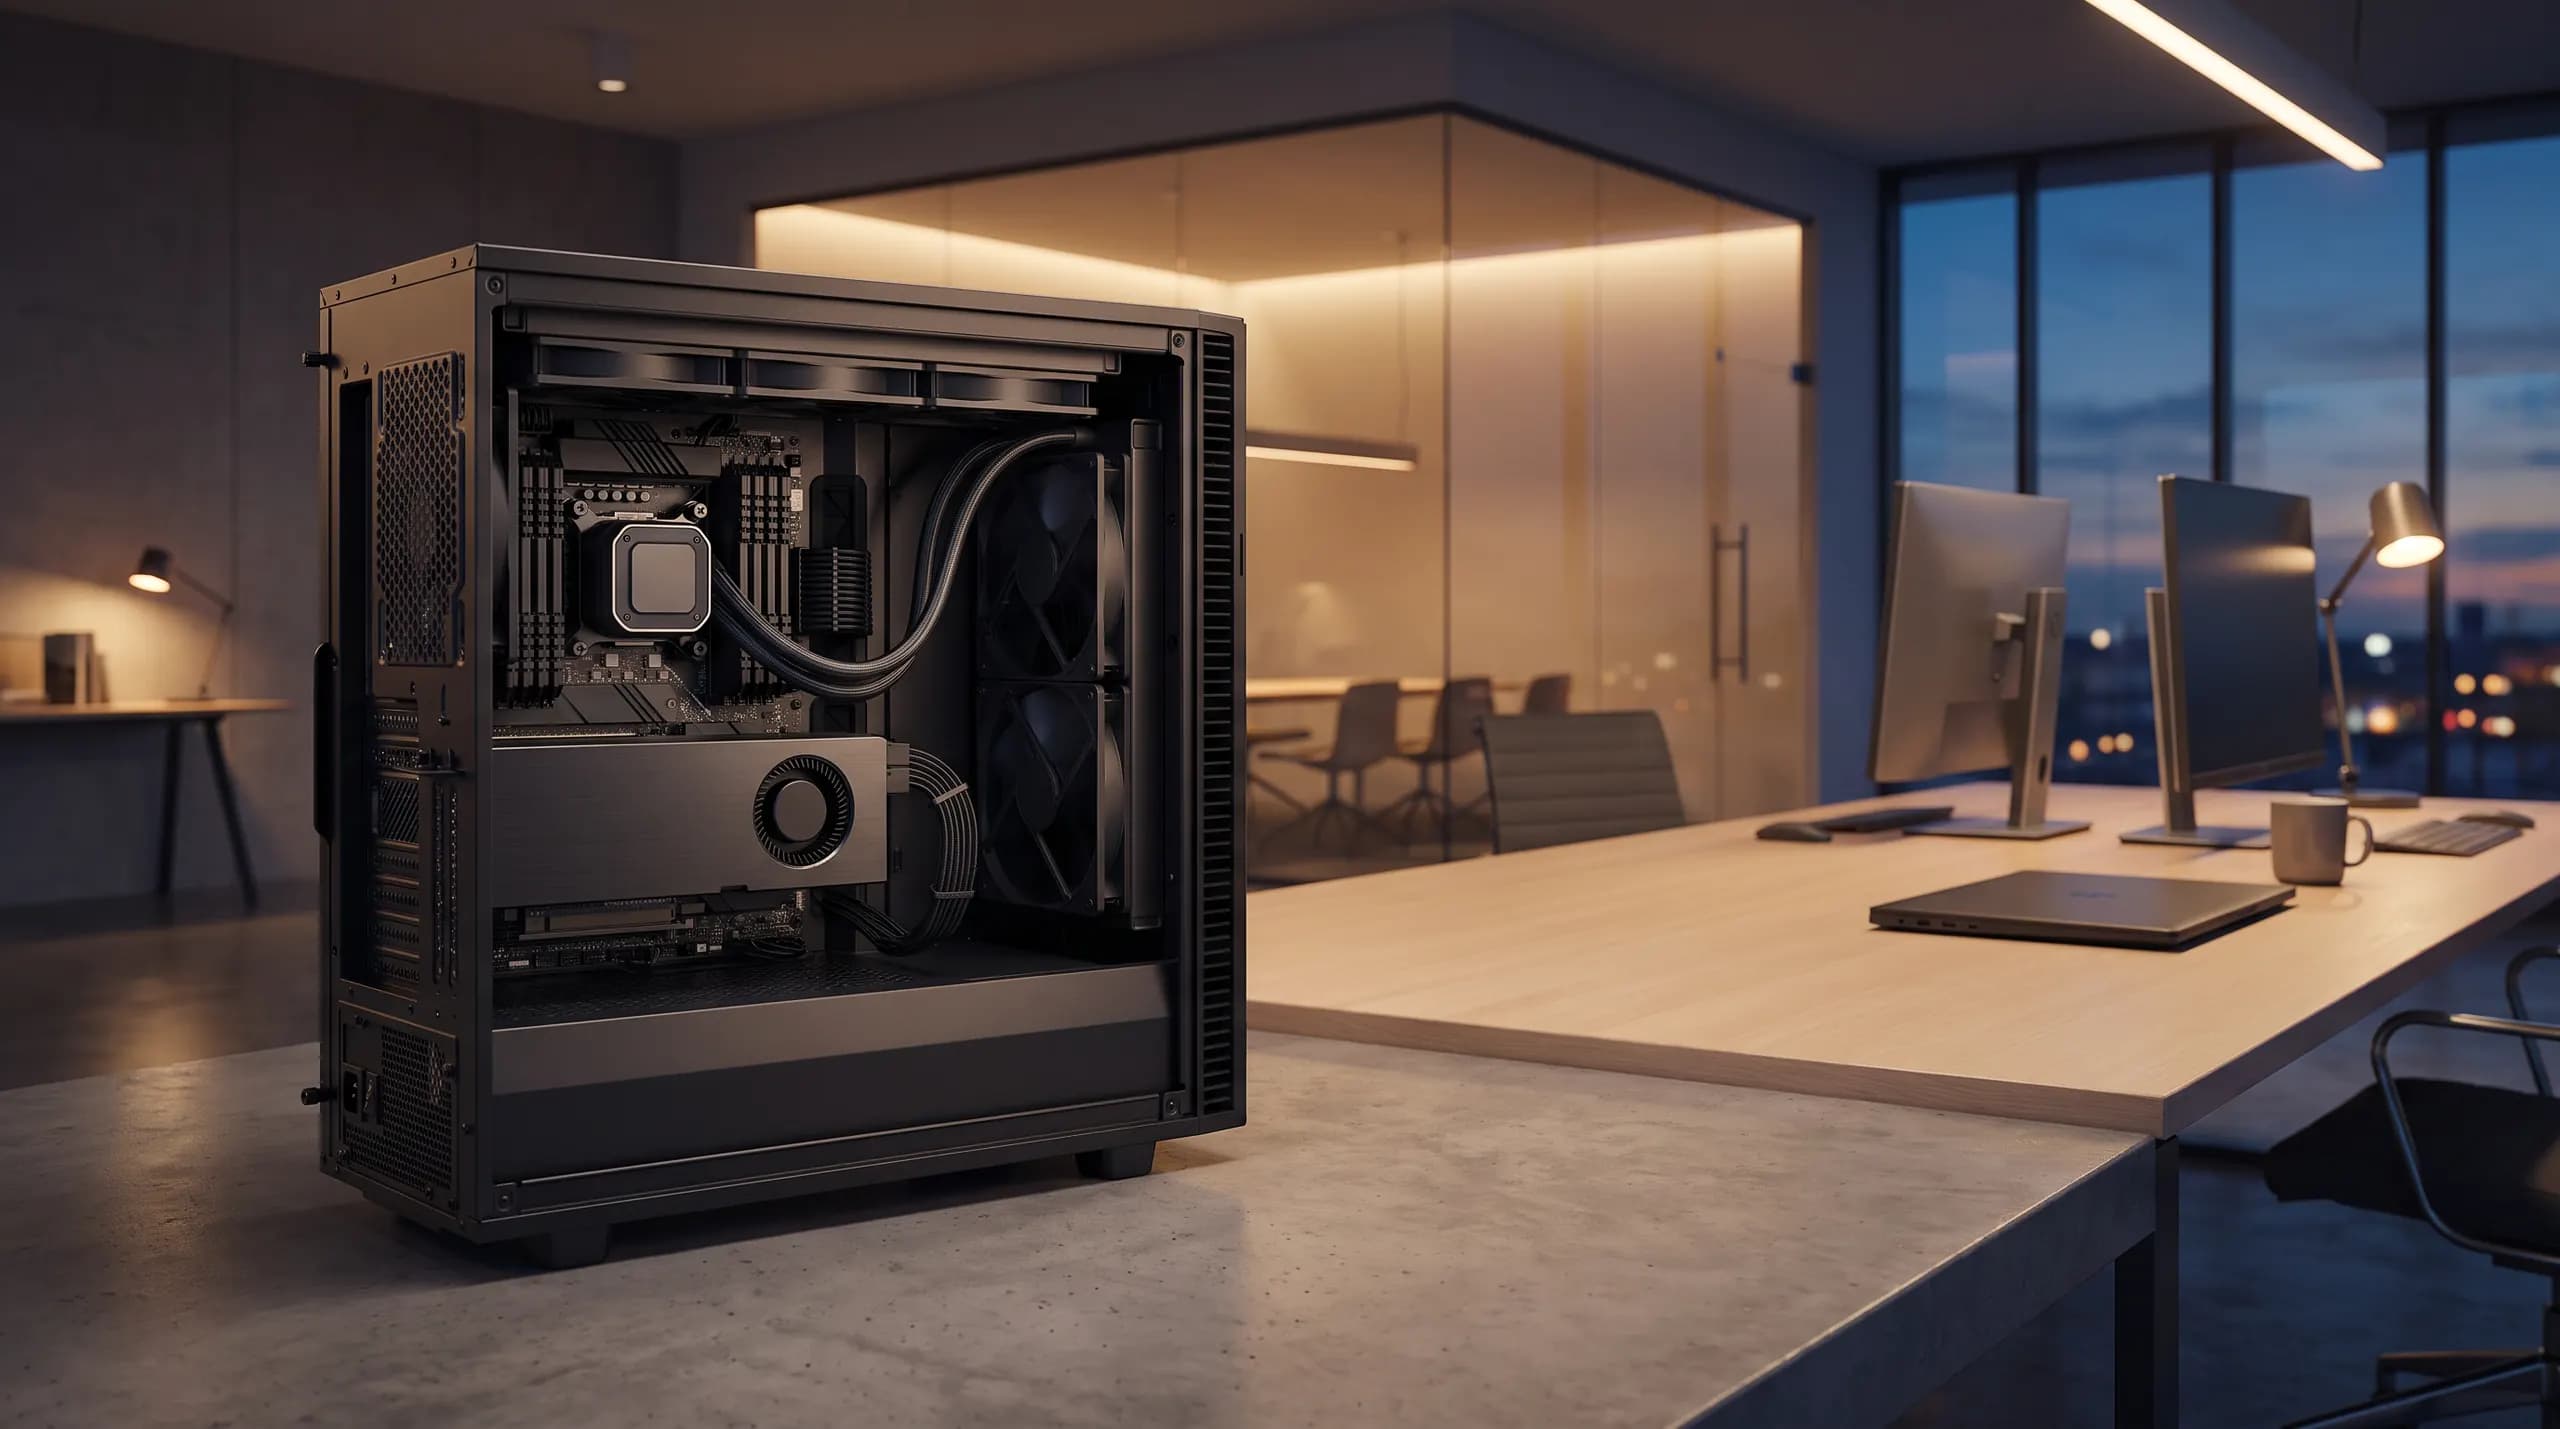
Studio render: our GPU serverNVIDIA RTX PRO 6000 Blackwell Server Edition
Best when the machine lives in a server room or a rack, shared by many people.
In our GPU servers, from ₹64 lakh. See GPU servers
Product images: NVIDIA. The Server Edition picture is our own studio render of a GPU server.
| Specification | Workstation Edition | Max-Q Edition | Server Edition |
|---|---|---|---|
| GPU memory | 96 GB GDDR7, ECC | 96 GB GDDR7, ECC | 96 GB GDDR7, ECC |
| Memory bandwidth | 1,792 GB/s | 1,792 GB/s | 1,597 GB/s |
| CUDA cores | 24,064 | 24,064 | 24,064 |
| Tensor and RT cores | 5th gen · 4th gen | 5th gen · 4th gen | 5th gen · 4th gen |
| FP32 performance | 125 TFLOPS | 110 TFLOPS | 120 TFLOPS |
| AI performance (FP4) | 4,000 TOPS | 3,511 TOPS | 4 PFLOPS |
| Power | 600 W | 300 W | Up to 600 W, configurable |
| Cooling | Two fans, air through the card | One blower fan | Passive: the server’s airflow |
| Size | Dual slot, 12 inches long | Dual slot, 10.5 inches long | Dual slot, full height and length |
| Shared between users (MIG) | Up to 4 isolated GPUs | Up to 4 isolated GPUs | Up to 4 isolated GPUs |
| Connection | PCIe Gen 5 | PCIe Gen 5 | PCIe Gen 5 |
Source: NVIDIA’s product page for each edition. AI performance is NVIDIA’s FP4 figure as each page gives it.
Three jobs where one machine serves a whole team. Serving answers and training models load it differently; tell us which you’ll do most.
One assistant for every department, answering from your policies, contracts and past projects once they are connected, on a machine inside your own office.
32 people asking togethermeasured with Qwen3.8 27B; the staff chat screen and document link are set up on request
Completions and code review for a whole engineering team, wired into their editors, with the source never leaving your network.
Up to 32 developerssized from our 32-person chat test; heavy autocomplete is timed on your own setup
Training your own networks in PyTorch with three times the memory of a 32 GB card, so larger models and batches fit without splitting.
One shared training boxfine-tuning a 70B model needs the Multi-GPU workstation

Real build
Assembled in Baner in September 2026, at about ₹32 lakh: the machine behind the 32-user test above.
The power supply and how much RAM you get change with every order; your committee gets the complete spec sheet with the quote.
Recent prices, GST in, from one H200 card up to an eight-card server; buyers stay anonymous. Data-centre cards have no fans of their own and need a server’s airflow.
8 workstation cards · 768 GB
₹2.1 crore
Sep 2026
2 data-centre cards · 282 GB
₹1.41 crore
Sep 2026
2 data-centre cards · 192 GB
₹93.7 lakh
Oct 2026
3 data-centre cards · 144 GB
₹82.9 lakh
Oct 2026
1 data-centre card · 141 GB
₹57.8 lakh
Oct 2026
2 RTX PRO 6000 · 192 GB
₹56.5 lakh
Sep 2026
1 RTX PRO 6000 · 96 GB
₹27.6 lakh
Oct 2026
₹20–45 lakh
GST included, spanning every Pro workstation quote we have sent since June 2026, each one itemised part by part.
Payback against renting one data-centre GPU from AWS Mumbai at its listed ₹213.96 an hour, 12 hours every day of the year: about 24 months for a ₹20 lakh build and about 38 for ₹32 lakh, net of GST input credit, power and maintenance. Model your own usage
From first message to a working machine is typically about a week. The card is sourced to order, so your quote fixes the date. Setup costs nothing, support is one phone number, and we are an authorised partner of AMD and NVIDIA.
Model, team size and budget, by form, phone or WhatsApp.
Each component priced, and our recommendation, even when that is a smaller machine.
Put together in Baner, held at full load, then set up and timed on your model.
Insured shipping across India or pickup in Pune, followed by a walkthrough call with your team.
On request only: a chat screen for your staff, a link into your document store, and user logins.
Four machines in the range. This one is the single-card team machine: its 96 GB takes the 70B and 120B models a 32 GB Desk AI PC can’t load.
One 32 GB card
A person or a small group; 27B-class models
₹3.5–11 lakh
Open its pageOne 96 GB RTX PRO 6000
A team of 32 asking together; models to 120B
₹20–45 lakh
You are hereTwo RTX PRO 6000, 192 GB
Beyond 32 users, or fine-tuning 70B
₹46–57 lakh
Open its pageUp to eight cards, 768 GB
Company-wide use and the largest models; server room
₹64 lakh–2.1 crore
Open its pageSizing, editions and power, the questions that come before a team machine is approved. Yours isn’t here? WhatsApp our engineers.
Count the people likely to press send in the same few seconds, not the payroll. In our test 32 simultaneous users each got about 63 tokens a second, with replies starting in 0.28 s. A larger headcount can share it, because not everyone asks at once; send us yours and how they will use it, and we size it.
The 5090 tops out at 32 GB; the RTX PRO 6000 carries 96 GB, and it is error-correcting (ECC) memory. For a 27B-class model and a small group, a Desk AI PC with a 5090 (the top end of its ₹3.5–11 lakh range) does the job. For 70B or 120B models, or 32 people together, it has to be the 96 GB card.
Both carry 96 GB. The Max-Q is capped at 300 W and pushes its heat out of the back of the case, which is why two to four can sit side by side. The Workstation Edition takes 600 W for the most speed from a single card, and needs a roomier case and supply. Our measured build runs the Max-Q.
Models up to 120B on one card. Room for far more conversations in memory: 1.71 million tokens of cache, against 0.23 million in our 32 GB RTX PRO 4500 test. More total output when many ask together: 1,752 against 1,085 tokens a second at 32 users, on the same model.
Our card held 300 W under sustained load. Add the processor’s rated 350 W and roughly 100 W for everything else (our estimate) and the machine is about 0.75 kW, or ₹7.60 per working hour at ₹10.11 a unit. Size the UPS for at least that load plus monitors and network gear.
Yes, if we plan it now: we fit a board and power supply with space for another Max-Q, so growing never means rebuilding. Two cards together is our Multi-GPU workstation, ₹46–57 lakh as a complete build.
Tell us the model, the headcount and how they work. You get an itemised spec within 4 working hours and a working machine in about a week, or our advice to go smaller, or to rent, if that suits you better.
We’ll send your itemised build spec within 4 working hours.
Hey. I'm VOLT — NVSX's AI assistant.
Ask me about products, build recommendations, compatibility — or anything PC hardware.